
Bojan Tunguz
@tunguz · 16 ago 2023
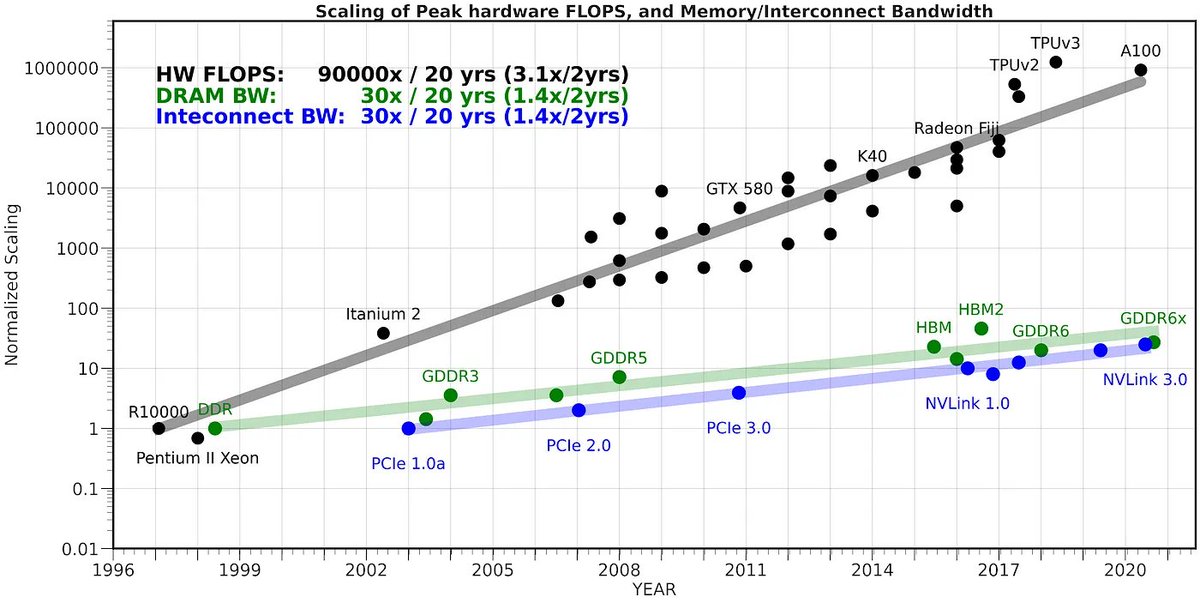
When it comes to inference, memory speed is much more important than logic speed.
 Andrej Karpathy@karpathy· 15 ago 2023
"How is LLaMa.cpp possible?"
great post by @finbarrtimbers
llama.cpp surprised many people (myself included) with how quickly you can run large LLMs on small computers, e.g. 7B runs @ ~16 tok/s on a MacBook. Wait don't you need supercomputers to work
Elon Musk
@elonmusk
Most large AI systems are currently extremely wasteful with how much energy is spent on data transfer (moving same bits around) vs compute.
Tesla estimate is that at least an order of magnitude improvement is possible.
07:31 · 16 de agosto de 2023 · 88 mil visualizaciones
90
94
1,2 mil